Most operations have thought hard about what happens when something breaks. Far fewer have thought about what happens when somebody plans to touch the site deliberately. Yet across a year, planned work almost certainly accounts for more offline hours than faults do: breaker servicing, firmware pushes, transformer testing, pool migrations, network changes, cooling system flushes. Each one is scheduled, each one is voluntary, and each one is a chance to take hashrate down for longer than intended.
Our guide to outage response and postmortems covers the unplanned half of this: who gets woken up, who decides, what gets checked first. This is the other half. The work you chose to do, on a date you picked, with time to prepare — and the discipline that separates a clean two-hour window from an all-night recovery.
A maintenance window is a scope, not a time slot
The most common failure is treating the window as a calendar entry. Somebody books Tuesday 02:00 to 06:00, and on Tuesday at 02:00 a technician starts work with only a general sense of what is in scope. By 04:00 the original task is done and somebody suggests also swapping the failing fan in container three, since the hall is down anyway. That second task is where windows overrun.
Write the scope before the date. A useful scope statement says what will change, what will be touched to make that change possible, and explicitly what will not be touched. The last part does most of the work. A window that says “replace the main breaker in panel B; no work on panels A or C; no firmware changes” gives the person on site permission to refuse a good idea at four in the morning, which is exactly when good ideas are most expensive.
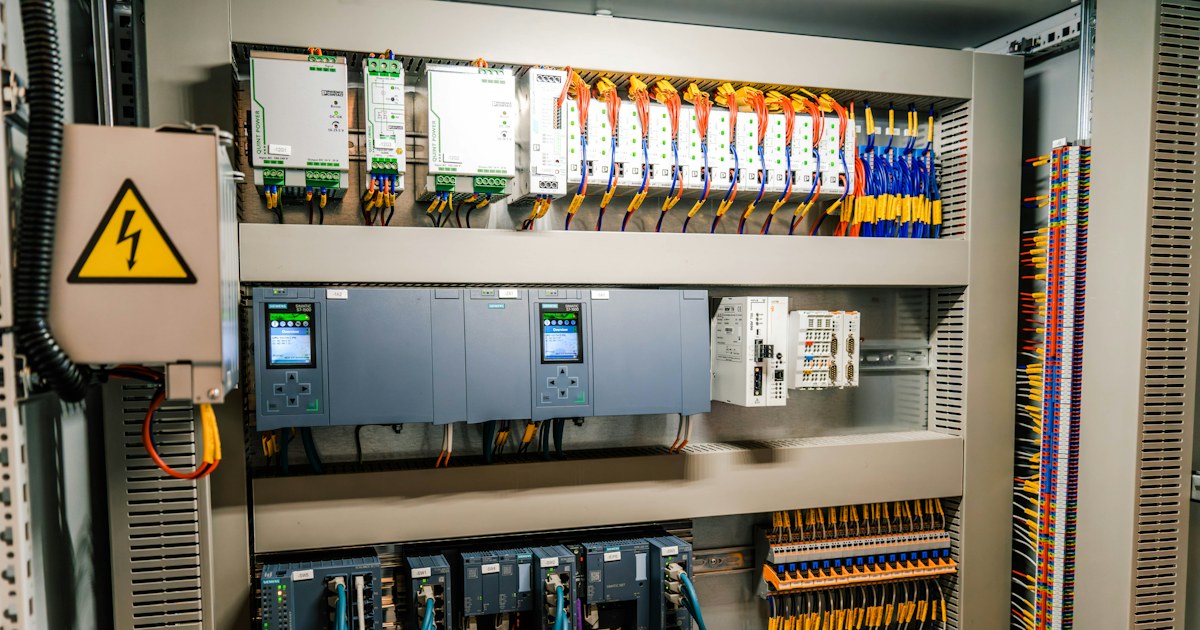
Scope also decides who needs to be there. Electrical work inside a live panel is not the same risk as a pool configuration change, and the switchgear and breaker maintenance side of the house carries isolation requirements that a software change does not. Bundling both into one window because they happen to be due the same week means the whole window inherits the stricter rules and the longer duration.
Size the window from the restart, not the task
Operators consistently estimate how long the work takes and then book that much time. The work is rarely the long part. Bringing a mining hall back is, and the asymmetry is easy to underestimate: shutting down is immediate and orderly, while starting up is staged, sequential and prone to discovering things that were already broken.
Machines that were running fine before a power cycle do not all come back. Units sitting on a marginal power supply, a tired fan or a hash board that was degrading quietly will often fail on restart rather than during operation — the thermal and electrical shock of a cold start is what finally exposes them. A site that goes down with every miner hashing can come back with a measurable number that do not, and finding them is part of the window, not an afterthought.
The electrical side has its own sequence. Energizing a hall all at once presents a large inrush to the transformer and upstream protection, which is why staged restart matters and why the black start procedure for a site is worth writing down before you need it. If your only documented restart sequence is the one in somebody’s head, the window is longer than you think.
A practical rule: estimate the task honestly, then estimate the restart and verification separately, and book the sum plus a margin. If the window is advertised to hosting customers, publish the longer figure. Finishing early is a good outcome. Running over is the thing that erodes trust.
Decide the back-out before you start
Every change needs an answer to one question asked in advance: if this does not work, how do we get back to where we were, and how long does that take? If the answer is unknown, the change is not ready to be made.
Some changes back out cleanly. A firmware push can be reversed if the previous image is on hand and somebody has actually confirmed it flashes. A pool configuration change can be reverted in minutes. Others do not back out at all. Once a breaker is out and a replacement is in, the old one is not going back; once a cooling loop is drained, refilling it is its own job with its own duration.
The useful distinction is not reversible versus irreversible but how long reversal takes compared with the window you have left. A change that takes twenty minutes to apply and ninety minutes to reverse needs a decision point partway through the window — a time at which, if the change is not working, you stop trying and start reversing. Name that time before you begin. Deciding it in the moment, with the site down and the clock running, is how a planned window becomes an unplanned outage.
Change one thing, and know what “working” means
When several changes go in together and the hall comes back wrong, you have no way to tell which one did it, and the diagnosis consumes the time you saved by batching. Where the work genuinely must be batched, sequence it so each step can be verified before the next begins.
Staging applies to fleet-wide changes in particular. A firmware version that looks fine on the bench can behave differently across a hall running at temperature. Pushing it to a small group first, letting them run long enough to show thermal behavior rather than just a successful boot, and only then rolling wider, costs one extra window and prevents the scenario where every machine on site needs reflashing.
Verification deserves the same rigor as the work. “The miners are back” is not a completion criterion. A window is finished when hashrate is at the level it was before, when the count of offline units matches or beats the pre-window count, when temperatures have settled rather than merely started falling, and when nothing new is alarming. Capture those numbers before you take the site down, because afterwards you will have nothing to compare against. The metrics in our guide to remote monitoring and fleet management are the ones worth recording on both sides of the window.
Tell people, and tell them the right things
If you host third-party machines, a maintenance window is a commercial event as much as a technical one. Customers do not generally object to planned work. They object to finding out from their own dashboard that their machines are down, and to being told afterwards that it was scheduled.
Notice should carry the window’s start and expected end, what is being done in plain terms, whether the downtime counts against the uptime commitment, and who to contact during it. That third point is where most disputes begin: many agreements exclude planned maintenance from uptime calculations, often with a monthly cap, and a customer who has not read that clause recently will reasonably expect a credit. Our explainer on colocation SLAs and uptime guarantees sets out how those exclusions are normally written. Say which side of the line this window falls on at the time you announce it, not after somebody asks.
Write down what happened
The step most often skipped is the shortest. After the window, record what was actually done, what the numbers were before and after, what went differently from the plan, and how long each phase really took. Three or four of those records turn window planning from guesswork into arithmetic, because you stop estimating restart time and start looking it up.
They also catch the slow problems. If the number of units that fail to return after a power cycle climbs across successive windows, that is a fleet ageing out, and it is visible in the maintenance records long before it is visible anywhere else. The cleaning and inspection intervals in our preventive maintenance guide are easier to justify when you can show what a cold start costs you now compared with a year ago.
Where to start if none of this exists
Take the next piece of planned work, whatever it is, and do four things. Write the scope, including what is explicitly out of it. Record the pre-shutdown numbers so you have something to verify against. Decide the back-out and the time at which you would use it. Afterwards, write a short note of what actually happened. That is most of the discipline, and none of it requires a tool or a budget.
The commissioning side of a new build is worth treating the same way: the procedures in our guide to load bank testing and commissioning exist precisely because proving a system under controlled conditions is cheaper than discovering its limits with a hall full of customer hardware behind it. And if the downtime arithmetic is what justifies the effort internally, our breakdown of what downtime actually costs gives you the number to put against an hour of overrun.
Operators who would rather this discipline sat with a staffed facility than with their own team are welcome to talk to us about hosting, where planned work, notice and restart verification are part of what the site does rather than something you schedule yourself.
Explore Rax Mining
- Bitcoin Miner Hosting — Tiered rates from $0.085/kWh, NatGas from $0.055/kWh
- NatGas MDU Units — 1MW modular datacenter containers
- Mining Profitability Calculator — Estimate your mining returns
- Our Facility — Tour our mining infrastructure