Most mining operations can tell you what an hour of downtime costs. Our guide to downtime costs sets out that arithmetic, and it is usually the number that justifies monitoring, redundancy and spare capacity.
Far fewer can tell you what actually happens in the first twenty minutes of an outage. Who gets woken up. Who is allowed to decide that the site stays down. What gets checked first. Who tells the hosting customers. Those questions get answered improvised, at night, by whoever happened to see the alert, and the quality of that improvisation is a large part of how long the outage lasts.
This is about that process, and about the step almost everyone skips afterward.
Monitoring is not response
Sites invest heavily in detection. Our guide to remote monitoring and fleet management covers the tooling, and most operations of any size have dashboards, hashrate alerting and environmental sensors.
Detection answers one question: something is wrong. It does not answer what to do, who does it, or who decides. An alert delivered to a group chat at 3 a.m. with nobody formally on duty is not a response capability. It is a notification that may or may not reach somebody who may or may not act.
The gap between a site that recovers quickly and one that does not is rarely the monitoring. It is almost always the twenty minutes after the alert.
Severity has to be defined before the event
The first decision in any incident is how big this is, and that decision drives everything after it. Making it in the moment produces inconsistency, because the answer depends on who is awake.
Define the levels in advance. The useful distinctions for a mining site are not about how many machines are affected but about what is at risk: whether equipment is in danger, whether the problem is spreading, and whether it is safe to be on site. A cooling failure in a hot hall escalates on its own and has a deadline attached. A single container offline does not, and dragging someone out at 3 a.m. for it is how you end up with nobody willing to carry the phone.
Write down what qualifies for each level and what each level entitles the responder to do, including the authority to shut things down. The hardest moment in an incident is a technician who can see that the site should come offline but is not sure they are allowed to make that call. That hesitation is expensive and entirely preventable.
The runbook is a short document, not a manual
A runbook that aims to be comprehensive will not be read during an incident. The version that works is short, specific to this site, and written for someone who is tired.
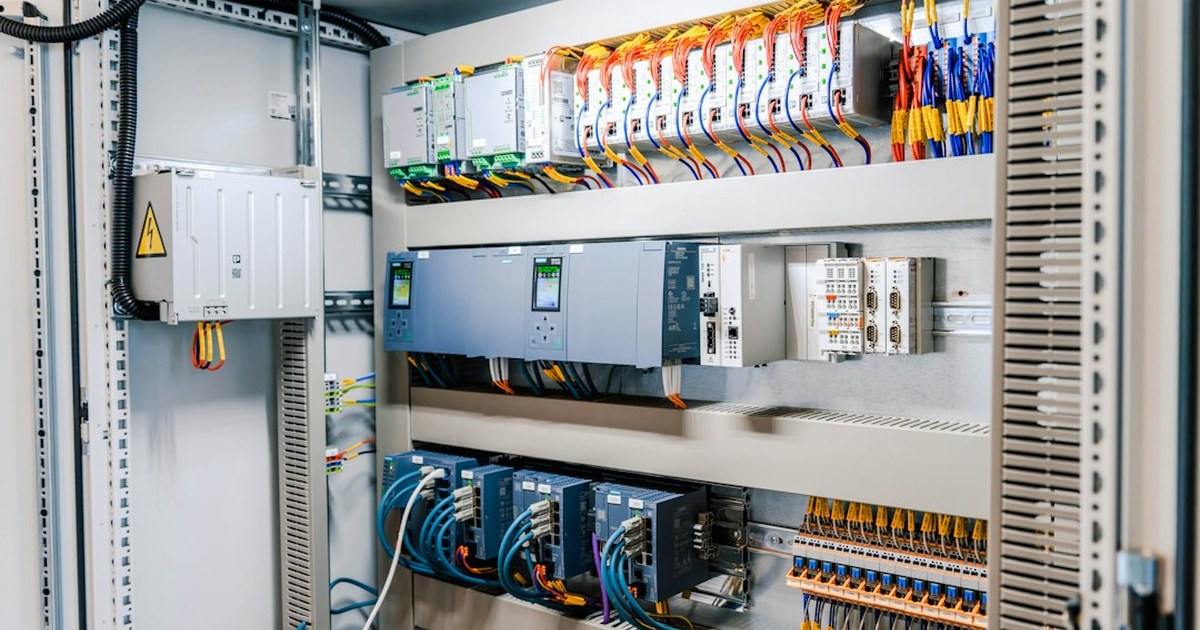
What belongs in it: the physical order to check things in, which reflects how this site actually fails rather than a generic flowchart; where the isolation points are and what they feed; the circumstances under which the correct action is to stop rather than investigate; and the contact chain, with the utility’s outage line and the account number alongside it, because looking that up during an outage wastes real minutes.
What does not belong in it: background explanation, equipment theory, or anything the reader could get later. The runbook is for the first thirty minutes.
Writing the check order honestly is harder than it sounds, because the instinct is to list everything. The useful version reflects what actually takes this site down and how fast each one hurts. Power and cooling carry deadlines: a hall with no airflow is damaging equipment while you diagnose, so confirming the thermal situation early is not thoroughness, it is triage. Network and pool connectivity cost revenue but harm nothing, so they can wait a few minutes without consequence.
Partial failures deserve explicit treatment, because they are more common than total ones and considerably more confusing. Half a site offline, a phase lost, one cooling train down, or a hashrate that has dropped without anything reporting a fault all present as ambiguous, and ambiguity is where responders lose time. A line in the runbook saying what to do when the picture does not make sense, which is usually to protect the equipment first and investigate second, is worth more than another diagnostic branch.
Keep a copy that does not depend on the site being up. A runbook on a network share behind a failed connection, or on a wiki nobody can reach because the site’s internet is the problem, is not available at the moment it is needed. Printed copies in the building and on responders’ phones are unglamorous and they work.
The restoration sequence deserves particular care, because bringing a site back is not the reverse of losing it. Energizing everything at once draws an inrush the system may not tolerate, and the order matters. Our guide to black start procedure covers that in detail, and a reference to it belongs in the runbook rather than a retelling of it.
Somebody has to actually be on duty
An on-call rota is a commitment that a specific named person is reachable and able to act in a defined window. It is different from a group chat, and the difference shows up at 3 a.m.
Making one work requires a few things that are easy to leave implicit. The person on duty needs the access to act, which means credentials, keys and gate codes that work tonight rather than ones that expired. They need a reachable escalation path to somebody with the authority to approve an expensive decision. And the rota needs enough people that it does not become one person who is permanently on call and eventually leaves. Our guide to staffing a mining operation covers the hiring and rota side of that.
Remote sites add travel time to every response, which changes what the rota is for. If the nearest technician is ninety minutes away, the valuable capability is remote diagnosis and remote shutdown, so that the drive only happens when it is genuinely necessary and the responder knows what they are driving to.
Communication is a parallel task, not an afterthought
For an operation hosting third-party hardware, customers find out about an outage one of two ways: from you, or from their own dashboards. The second is considerably worse, and the difference in how it is received is out of proportion to the difference in information.
Assign the communication to someone who is not the person fixing the problem. A responder who is also fielding questions is a responder working slowly. Agree what gets said at the start, what gets said periodically while it is unresolved, and what gets said at the end, and accept that an early message saying only that you are aware and investigating is worth sending even though it contains nothing.
The postmortem is the part that pays
When the site comes back, the incident is over and attention moves on. That is the moment the lasting value is available and almost always forfeited.
A postmortem is a short written record of what happened, in what order, why, and what will change. It does not need to be long. It needs to exist, and it needs to be written while people still remember, which in practice means within a few days rather than when someone gets to it.
Two things make it worth doing. The first is that the stated cause is frequently not the real one. A failed component is an explanation; why it failed without warning, and why nobody knew until the site stopped, usually is not answered by naming the part. Our guide to predictive maintenance exists largely because of failures that looked sudden and were not.
The second is that the postmortem is what turns one site’s bad night into something the whole operation knows. A fix that lives only in the head of whoever was on call leaves with them.
It has to be blameless to work. A process that produces consequences for the person who was present produces careful, uninformative write-ups, and the detail you needed is exactly what gets omitted. The subject is the system that allowed the failure to reach production, not the individual who happened to be holding it.
Track the actions it generates like any other work. A postmortem whose recommendations are never implemented is a filing exercise, and after a couple of those people correctly stop taking them seriously.
Where to start
If none of this exists, the highest-value hour is not writing a document. It is asking what happened during the last real outage: who found out, how long until somebody acted, what they checked first, who decided, and what has changed since. That conversation produces the first draft of the runbook and usually exposes one or two gaps worth fixing immediately.
Then write down the severity levels, name who is on duty and when, put the contact chain somewhere reachable when the site is not, and commit to a short write-up after anything significant. None of it is expensive. It is simply work that never feels urgent until the night it would have been.
Operators who would rather have a staffed facility carry this can place machines with one. Our breakdown of hosting costs per kilowatt-hour covers what that includes, and you are welcome to speak with our team about either approach.
Explore Rax Mining
- Bitcoin Miner Hosting — Competitive rates from $0.075/kWh
- NatGas MDU Units — 1MW modular datacenter containers
- Mining Profitability Calculator — Estimate your mining returns
- Our Facility — Tour our mining infrastructure